V. Madineni

Open to machine learning and data science roles

Vengaiah Madineni

Data Scientist · Machine Learning & Predictive Modeling

Four years building ML and statistical models for financial services and customer analytics: behavior, risk, fraud and retention, with Python, SQL, Scikit-learn and XGBoost. I turn complex data into production-ready models that stakeholders act on.

  • 4+ yrsbuilding ML and statistical models
  • 300K+records modeled at Synchrony
  • ~15%model performance gain from tuning
  • 20%less recurring data preparation effort
010203040506 Explore · EDAEngineer features Train & tuneValidate DeployMonitor RETRAIN LOOP FROM DATA TO DEPLOYMENT
Fig. 1 · How I work, end to end

About

Careful modeling, from first exploratory pass to monitored production model.

My open-source projects each target a specific way analysis goes wrong: future data leaking into features, noisy comparisons declared as wins, tiny slices raising false alarms, and covariates measured after treatment. Each ships with tests and a guard that refuses the unsafe answer.

Discipline
Data Science & Machine Learning
Base
Arlington, TX
Degree
M.S. Applied Statistics and Data Science, UT Arlington

Projects

Ten open-source builds, each one a guard against a specific way analysis goes wrong. Six in full, four in brief. All run on synthetic data.

Swipe through the sheets → Sheet 1 of 10

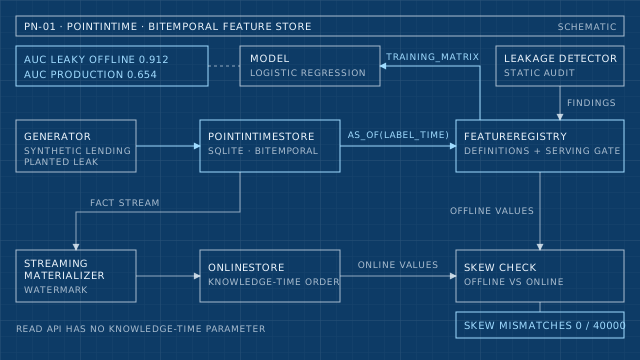
Data flow of pointintime: a synthetic lending generator feeds a bitemporal store, a registry gate, a leakage detector and a skew check

Sheet 01 · ML infrastructure

pointintime

A bitemporal feature store in which point-in-time correctness is enforced by the read API. A static leakage detector quarantines a deliberately planted future-leaking feature, and a train/serve skew check compares offline and online values.

  • Python
  • SQLite
  • Logistic Regression
  • Feature Engineering
  • unittest
  • GitHub Actions
Results
  • A naive latest-value join scores 0.912 AUC offline against 0.654 on production inputs; honest point-in-time features score 0.701
  • Knowledge-time watermark gives 0 of 40000 skew mismatches versus 3492 mismatches at 8.73% for the event-time bug
  • 59 tests covering the store, detector, registry gate and materializer
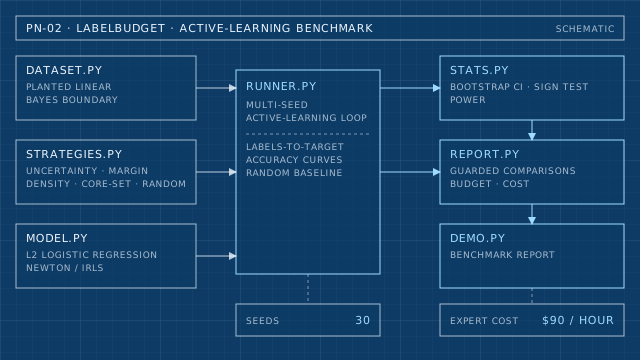
Data flow of labelbudget: dataset, strategies and model feed a multi-seed runner, statistics and a guarded report

Sheet 02 · Active learning

labelbudget

An active-learning benchmark that reports labels needed to reach a target accuracy, with variance across many seeds and a prominent random-sampling baseline. A comparison guard refuses to declare a winner the evidence does not support.

  • Python
  • Logistic Regression
  • Bootstrap Statistics
  • Active Learning
  • unittest
  • GitHub Actions
Results
  • Shows one seed claiming uncertainty sampling is 4.2x better while another shows random 2.1x better
  • Paired bootstrap CI and exact sign test over 30 seeds; no comparative claim below 10 seeds
  • Converts label budgets into cost at $90/hour and 6 min/label
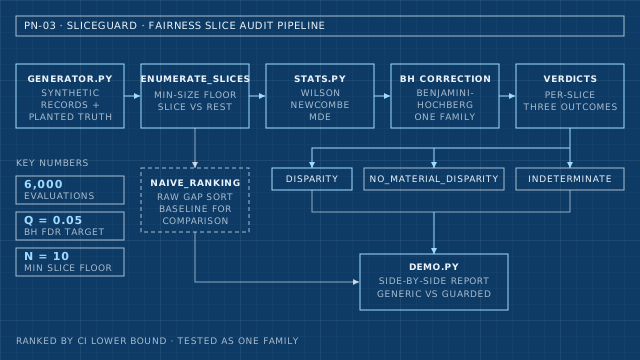
Data flow of sliceguard: records are sliced, tested with Wilson and Newcombe intervals, corrected and given verdicts

Sheet 03 · Model fairness

sliceguard

A fairness slice auditor that puts Wilson and Newcombe intervals on every slice, applies Benjamini-Hochberg correction and reports a minimum detectable effect, so tiny slices stop producing false alarms.

  • Python
  • Statistical Testing
  • Wilson Intervals
  • Benjamini-Hochberg
  • unittest
  • GitHub Actions
Results
  • Audits 6,000 synthetic underwriting-model evaluations with two planted 9-point disparities
  • A 19-person slice topping the raw-gap ranking is correctly marked INDETERMINATE
  • Ranks slices by the lower bound of the gap interval at a default q = 0.05
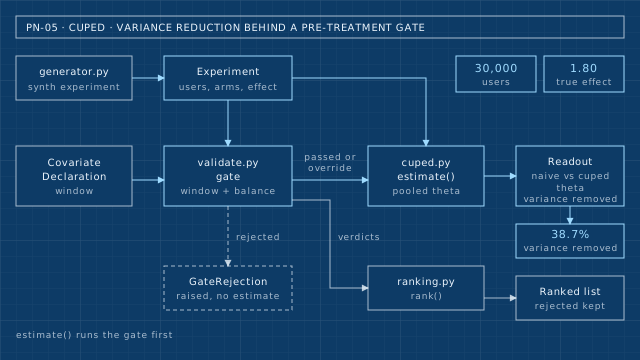
Data flow of cuped: an experiment and covariate declaration pass a validation gate before the CUPED estimate and readout

Sheet 04 · Experimentation

cuped

A CUPED variance-reduction library for A/B tests that refuses covariates measured after randomization, using a declared-window check plus a balance test across arms.

  • Python
  • A/B Testing
  • Variance Reduction
  • Statistical Inference
  • unittest
  • GitHub Actions
Results
  • Valid pre-period covariate removes 38.7% of variance: an 11-week test becomes a 7-week one
  • Blocks a post-treatment covariate that removes 98.3% of variance but returns an effect of -6.601 against a true 1.80
  • Seeded run on 30,000 synthetic customers with heavy-tailed revenue
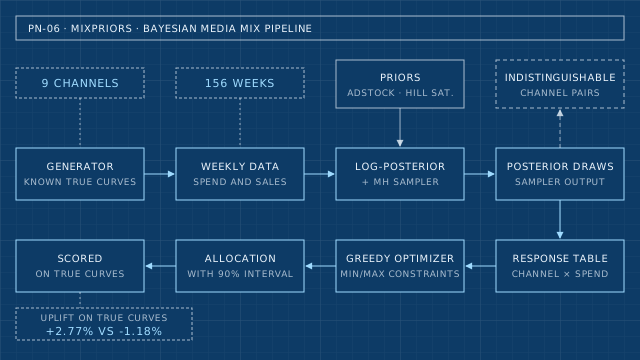
Data flow of mixpriors: synthetic data and priors feed a Metropolis-Hastings sampler, posterior draws and a budget optimizer

Sheet 05 · Bayesian modeling

mixpriors

A Bayesian media mix model with informative adstock and Hill saturation priors and a hand-written Metropolis-Hastings sampler. Its budget optimizer maximizes expected return across all posterior draws.

  • Python
  • Bayesian Inference
  • MCMC
  • JavaScript
  • unittest
  • GitHub Pages
Results
  • 9/9 true channel values inside their 90% intervals on 156 weeks of synthetic data
  • Posterior-aware plan scores +2.77% on the true curves versus -1.18% for the point-estimate shortcut
  • Browser lab deployed to GitHub Pages for risk-penalized allocation
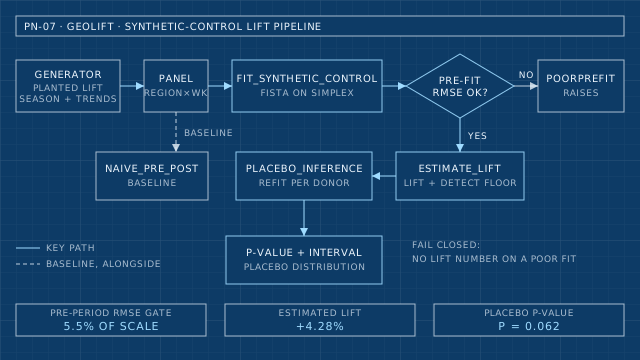
Data flow of geolift: a panel generator feeds a synthetic control fit, a pre-period gate, lift estimate and placebo inference

Sheet 06 · Causal inference

geolift

Geo incrementality testing by synthetic control with a pre-period fit gate and placebo inference, plus a browser demo of the gate-then-placebo decision.

  • Python
  • Synthetic Control
  • FISTA
  • Placebo Inference
  • JavaScript
  • GitHub Pages
Results
  • Estimates +4.28% lift against a planted 4.0%, where a before/after comparison reports -22.3%
  • Refuses fits whose pre-period RMSE exceeds 5.5% of scale and lifts below the detection floor
  • Placebo inference over 15 donors gives p = 0.062
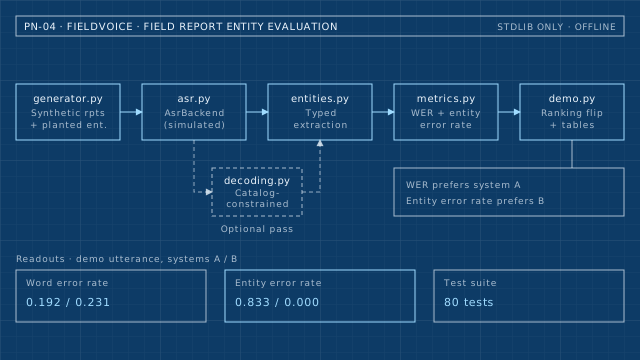
Data flow of fieldvoice: a generator and simulated recognizer feed entity extraction, constrained decoding and entity error rate metrics

Sheet 07 · Speech evaluation

fieldvoice

An offline speech-to-report pipeline scored on entity error rate instead of word error rate, with catalog-constrained decoding.

  • Python
  • Entity Extraction
  • Constrained Decoding
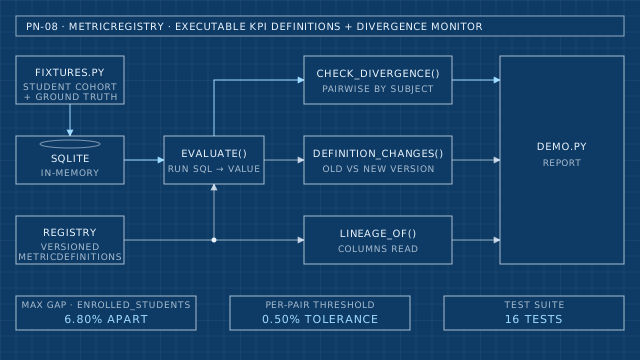
Data flow of metricregistry: versioned metric definitions run as SQL against SQLite, then a divergence monitor, change log and lineage

Sheet 08 · Data quality

metricregistry

A KPI registry of versioned, executable SQL with a monitor that alerts when metrics meant to match drift apart.

  • Python
  • SQL
  • Data Lineage
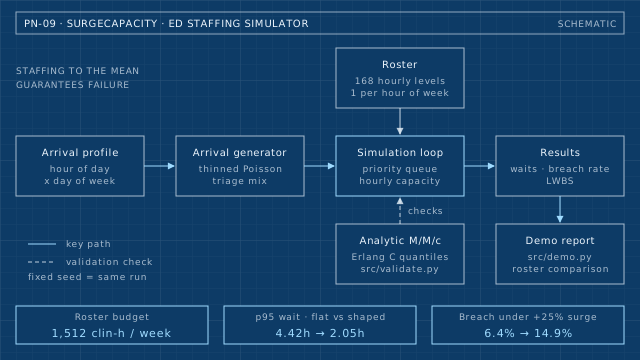
Data flow of surgecapacity: an arrival profile and hourly roster feed a discrete-event simulation, validated against analytic M/M/c results

Sheet 09 · Simulation

surgecapacity

A discrete-event simulation of emergency department staffing that reports p95 wait and breach probability, validated against M/M/c results.

  • Python
  • Discrete-Event Simulation
  • Queueing Theory
P2P EXCEPTIONS · COST-WEIGHTED PARETO price offcontract shortdelivery missingreceipt overdelivery PO linerounding bars: cost by cause · line: cumulative share

Sheet 10 · Procure-to-pay

p2pexceptions

Invoice exception analysis that classifies each failed three-way match into exactly one cause and ranks causes by cost with a Pareto.

  • Python
  • Pareto Analysis
  • Cost Weighting

Experience

Four-plus years shipping predictive and statistical models in financial services and customer analytics.

Synchrony

Financial Data ScientistFeb 2025 – PresentUSACurrent

Develop and deploy machine learning and statistical models in Python and Scikit-learn across customer, account, transaction and operational datasets of 300K+ records.

Highlights
  • Build predictive models for customer behavior, risk, credit, fraud and retention, supporting 8+ business use cases across financial and customer analytics.
  • Improve selected model performance by approximately 15% through hyperparameter tuning, cross-validation and error analysis, evaluating with precision, recall, F1-score, ROC-AUC, RMSE and MAE.
  • Improve analytical data quality by 18% through structured preprocessing, missing-value treatment and validation during EDA and feature engineering.
  • Use SQL to create reusable analytical datasets and feature pipelines, reducing recurring data preparation effort by 20% across 6+ machine learning workflows.
  • Apply XGBoost, classification, clustering and supervised/unsupervised learning across 12+ modeling experiments using behavioral and transactional features.
  • Python
  • SQL
  • Scikit-learn
  • XGBoost
  • Machine Learning
  • Statistical Modeling
  • EDA
  • Feature Engineering
  • Classification
  • Clustering
  • Cross-Validation
  • Hyperparameter Tuning

Cybage Software

AI/ML Data ScientistJan 2021 – Jul 2023India

Developed machine learning and statistical models for business, customer and operational analytics on datasets of 150K+ records across multiple analytical initiatives.

Highlights
  • Built supervised and unsupervised models using Scikit-learn, XGBoost, Random Forest and Gradient Boosting, evaluating 10+ model configurations across business use cases.
  • Improved selected model performance by approximately 12% across iterative experiments through hyperparameter tuning, cross-validation, model evaluation and error analysis.
  • Reduced recurring data preparation time by 15% through reusable Python and SQL workflows for cleaning, preprocessing, EDA and feature engineering.
  • Applied feature selection, transformation, encoding, scaling and dimensionality reduction across 20+ candidate variables to improve model inputs.
  • Used SQL, Python, Matplotlib and Seaborn for analytical datasets, visualizations and customer segmentation across 6+ recurring analytical workflows.
  • Python
  • SQL
  • Scikit-learn
  • XGBoost
  • Random Forest
  • Gradient Boosting
  • Matplotlib
  • Seaborn
  • Statistical Analysis
  • Feature Engineering
  • Customer Segmentation

Skills

The toolkit, grouped by the stage of the modeling lifecycle it serves.

Swipe through the groups →

Data & Features

  • Pandas
  • NumPy
  • Data Wrangling
  • Feature Selection
  • Encoding
  • Scaling
  • Dimensionality Reduction
  • Missing Value Treatment

Machine Learning

  • Random Forest
  • Gradient Boosting
  • Supervised Learning
  • Unsupervised Learning
  • Predictive Modeling
  • Model Calibration
  • Anomaly Detection

Model Evaluation

  • Error Analysis
  • Model Comparison
  • Precision / Recall
  • F1-Score
  • ROC-AUC
  • RMSE
  • MAE

Statistics

  • Hypothesis Testing
  • Correlation Analysis
  • Trend Analysis
  • Cohort Analysis
  • Outlier Analysis
  • Statistical Experimentation

Delivery

  • Reusable Feature Pipelines
  • Model Deployment
  • Model Monitoring
  • Model Retraining
  • Production Validation
  • Data Validation

Analytics & Visualization

  • Risk Analytics
  • Fraud Analytics
  • Retention Analytics
  • Portfolio Analytics
  • Data Visualization
  • Analytical Reporting
  • Analytical Storytelling

Education

Statistics and data science, built on an engineering foundation.

University of Texas at Arlington

Master of Science · Applied Statistics and Data Science

Dec 2024Arlington, TX

Dhanekula Institute of Engineering and Technology

Bachelor of Technology · Electronics and Communication Engineering

May 2023Vijayawada, AP

Contact

Let’s build a model that holds up

Looking for someone to build, validate and deploy machine learning models for risk, fraud or customer analytics? Reach out by email or phone.